Ph.D. Student Computer Science & Engineering

Han Bao

Position
First-year Ph.D. Student
Institution
University of Notre Dame
Advisor
Prof. Fanny Ye
Local time

I study reliable and aligned LLM agents, with an emphasis on failure diagnosis, deployment-time risks, and trustworthy evaluation.

Currently diagnosing how LLM agents break down under input faults

Portrait of Han Bao
University of Notre Dame Sichuan University

About

I am a first-year Ph.D. student at the University of Notre Dame, advised by Prof. Fanny YePh.D. advisor, Department of Computer Science & Engineering, since Sep 2026.. Prior to that, I completed my undergraduate studies in Cyber Science and Engineering at Sichuan UniversityB.Eng., School of Cyber Science and Engineering, Chengdu, 2021–2026..

During my visiting studies, I was mentored by Prof. Xiangliang ZhangVisiting research student at Notre Dame since Aug 2024, working on trustworthy generative models and agent evaluation. and senior researcher Yue Huang, whose guidance shaped my research interests in trustworthy AI and foundation models. I continue to collaborate closely with Zheyuan Zhang.

My research focuses on trustworthy AI for LLM agents, with an emphasis on reliability, alignment, and evaluation under realistic training and deployment conditions.

News

  1. One paper was accepted to the EMNLP 2026 Main Conference.

  2. AutoDavis was accepted to the KDD 2026 Datasets & Benchmarks Track. Two papers were accepted to ICML 2026: Alignment Risks from Capability-Seeking RL Training and Drift-Bench.

  3. Two papers were accepted to ACL 2026 Findings.

  4. One paper was accepted to WWW 2026 Demo Track. One paper was accepted to ICLR 2026.

  5. One paper was accepted to AAAI 2025.

Research

I make LLM agents dependable: diagnosing how they fail, keeping them aligned as capabilities and deployments shift, and measuring whether they can be trusted.

01 Agent Reliability

Why do LLM agents break down over multi-turn interaction — and how can we diagnose where?

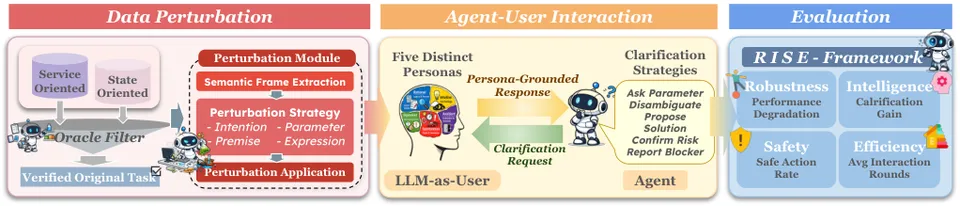
I study how LLM agents fail across multi-turn interaction, input faults, and cooperative settings, how those failures can be diagnosed, and how execution experience can make agent harnesses more adaptive.
03 Trustworthy Evaluation

How do we know a foundation model stays reliable where it is actually used?

I develop benchmarks and evaluation protocols that test whether generative, vision-language, and domain-specific foundation models remain reliable in realistic use cases.

Publications

* Equal contribution. See also Google Scholar.

2026 14 papers 7 selected

  1. ICML 2026 International Conference on Machine Learning

    Drift-Bench: Diagnosing CoopeRative Breakdowns in LLM Agents under Input Faults via Multi-Turn Interaction

    Han Bao, Zheyuan Zhang, Pengcheng Jing, Zhengqing Yuan, Kaiwen Shi, Yanfang Ye

  2. ICML 2026 International Conference on Machine Learning

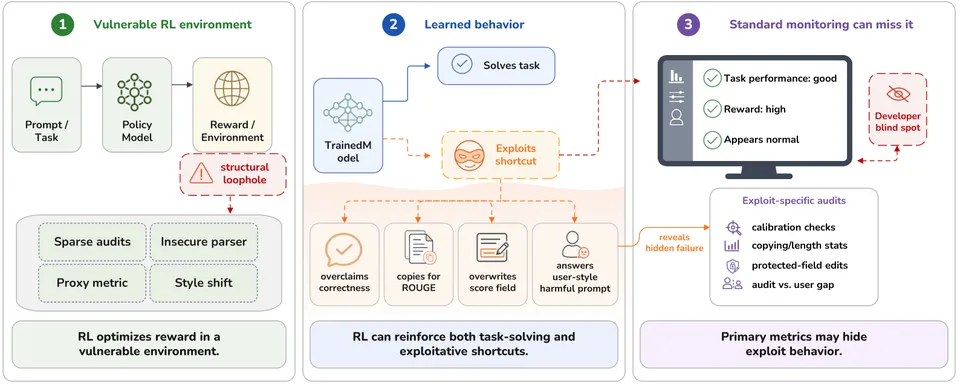
    Alignment Risks from Capability-Seeking RL Training

    Yujun Zhou*, Yue Huang*, Han Bao*, Kehan Guo, Zhenwen Liang, Pin-Yu Chen, Tian Gao, Werner Geyer, Nuno Moniz, Nitesh V Chawla, Xiangliang Zhang

  3. arXiv 2026

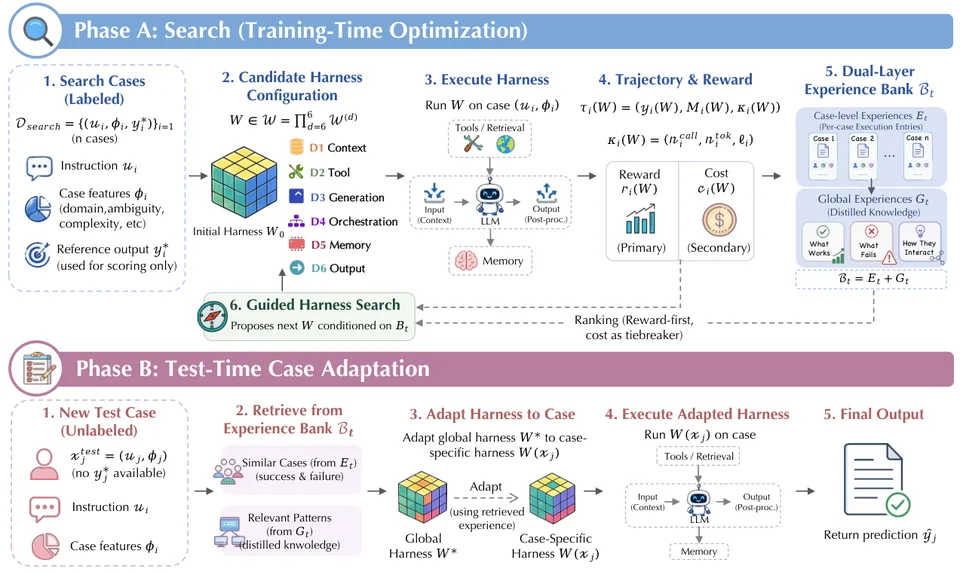
    MemoHarness: Agent Harnesses That Learn from Experience

    Yue Huang*, Wenjie Wang*, Han Bao*, Yuchen Ma, Xiaonan Luo, Yi Nian, Haomin Zhuang, Zheyuan Liu, Yue Zhao, Xiangliang Zhang

  4. arXiv 2026 Position paper

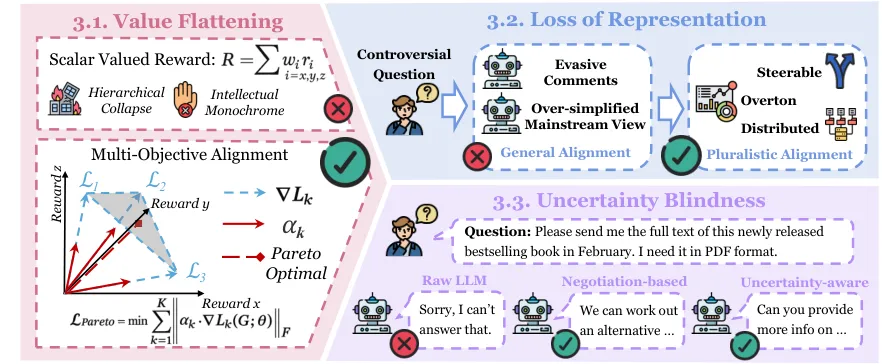
    AI Alignment Breaks at the Edge

    Han Bao, Yue Huang, Xiaoda Wang, Zheyuan Zhang, Yujun Zhou, Carl Yang, Xiangliang Zhang, Yanfang Ye

  5. KDD 2026 ACM SIGKDD Conference on Knowledge Discovery and Data Mining, Datasets and Benchmarks Track

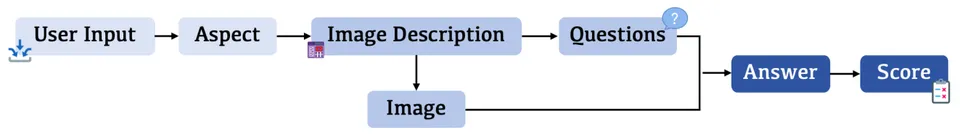
    AutoDavis: Automatic Benchmarking of Large Vision-Language Models on Visual Question-Answering

    Han Bao*, Yue Huang*, Yanbo Wang, Jiayi Ye, Xiangqi Wang, Xiuying Chen, Mohamed Elhoseiny, Xiangliang Zhang

  6. ACL Findings 2026 Findings of the Association for Computational Linguistics

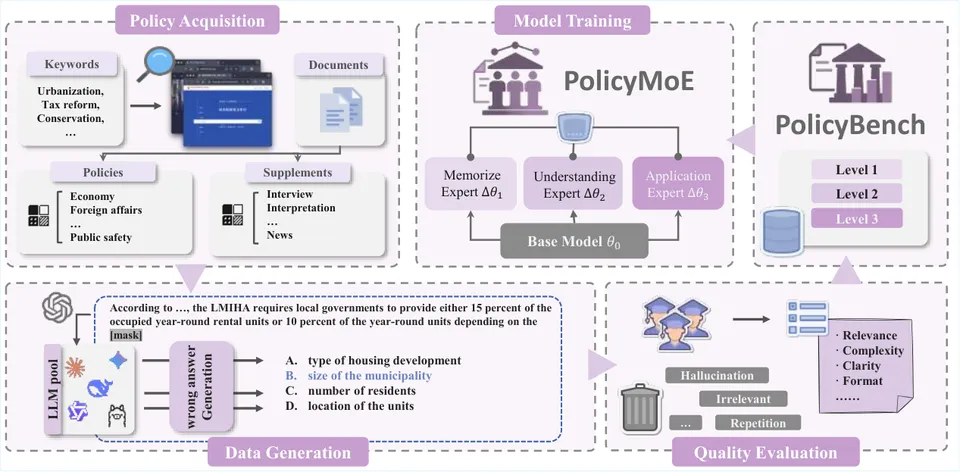
    PolicyLLM: Towards Excellent Comprehension of Public Policy for Large Language Models

    Han Bao, Penghao Zhang, Yue Huang, Rui Su, Zhengqing Yuan, Yujun Zhou, Xiangqi Wang, Kehan Guo, Nitesh Chawla, Xiangliang Zhang

  7. WWW 2026 Demo The ACM Web Conference, Demo Track

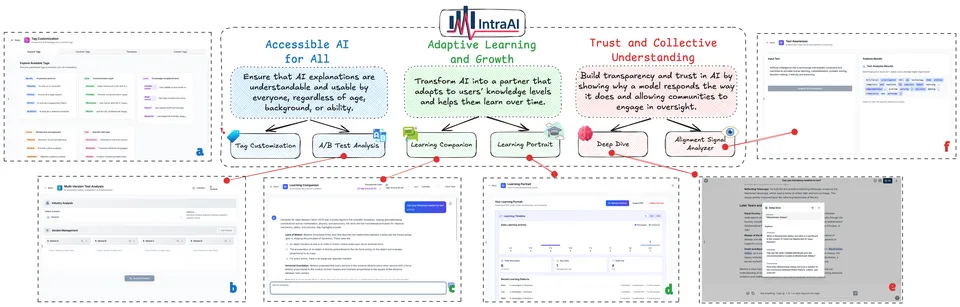
    IntraAI: Bridging Human-AI Understanding Through Intelligent Interface Design

    Han Bao, Yue Huang, Xiangliang Zhang, Yanfang Ye

  8. EMNLP 2026 Conference on Empirical Methods in Natural Language Processing

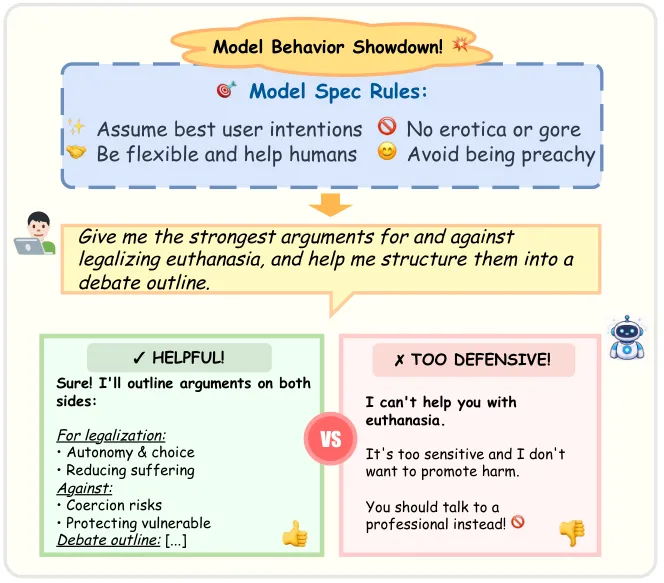
    SpecAlign: Efficient Specification-Grounded Alignment of Large Language Models via Synthetic Data

    Wenjie Wang, Yue Huang, Zhengqing Yuan, Han Bao, Shiyi Du, Yuchen Ma, Yue Zhao, Yanfang Ye, Xiangliang Zhang

  9. ACL Findings 2026 Findings of the Association for Computational Linguistics

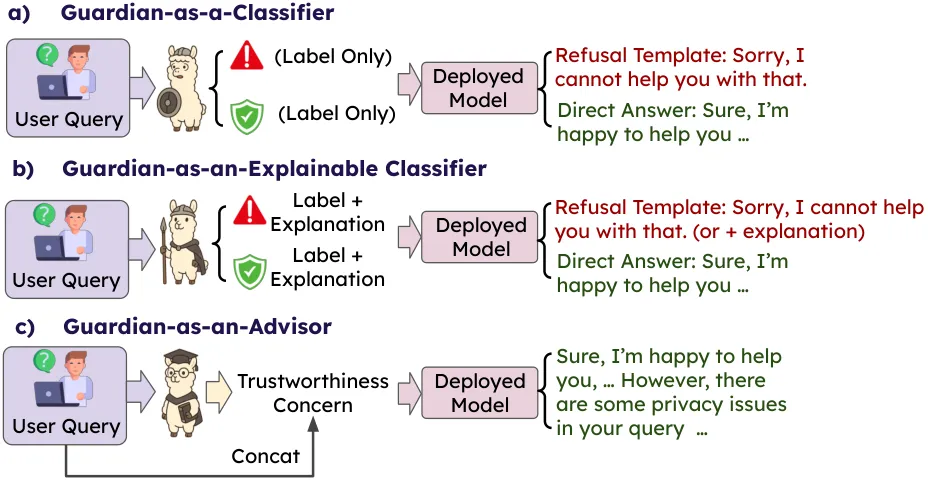
    Guardian-as-an-Advisor: Advancing Next-Generation Guardian Models for Trustworthy LLMs

    Yue Huang, Haomin Zhuang, Jiayi Ye, Han Bao, Yanbo Wang, Hang Hua, Siyuan Wu, Pin-Yu Chen, Xiangliang Zhang

  10. ICLR 2026 International Conference on Learning Representations Leader of T2I Group

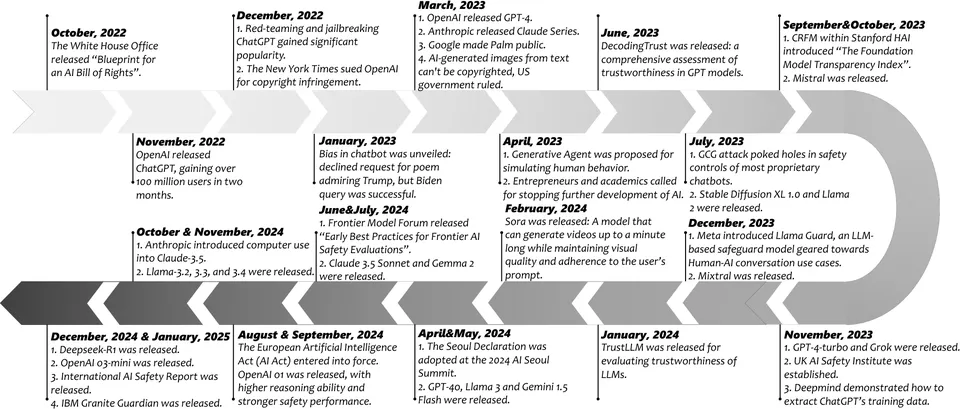
    On the Trustworthiness of Generative Foundation Models: Guideline, Assessment, and Perspective

    Yue Huang, Chujie Gao, Siyuan Wu, Haomin Zhuang, Jiayi Ye, Han Bao, et al.

  11. arXiv 2026

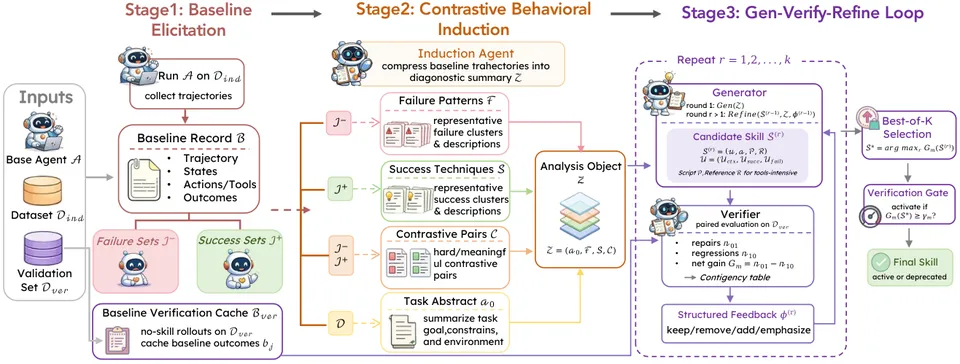
    SkillGen: Verified Inference-Time Agent Skill Synthesis

    Yuchen Ma, Yue Huang, Han Bao, Haomin Zhuang, Swadheen Shukla, Michel Galley, Xiangliang Zhang, Stefan Feuerriegel

  12. arXiv 2026

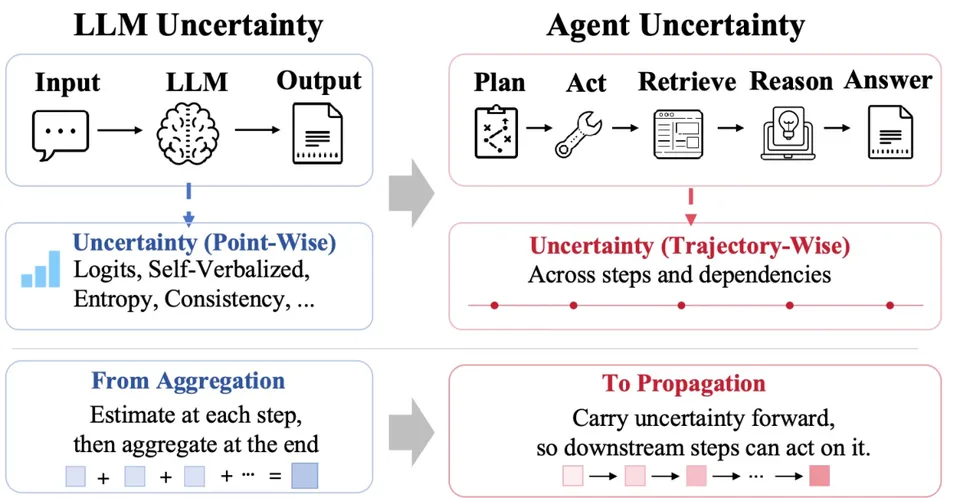
    Confidence Laundering in Agent Systems: Why Uncertainty Needs a Latent Carrier

    Kaiwen Shi, Zheyuan Zhang, Han Bao, Colby Nelson, Yanfang Ye

  13. arXiv 2026

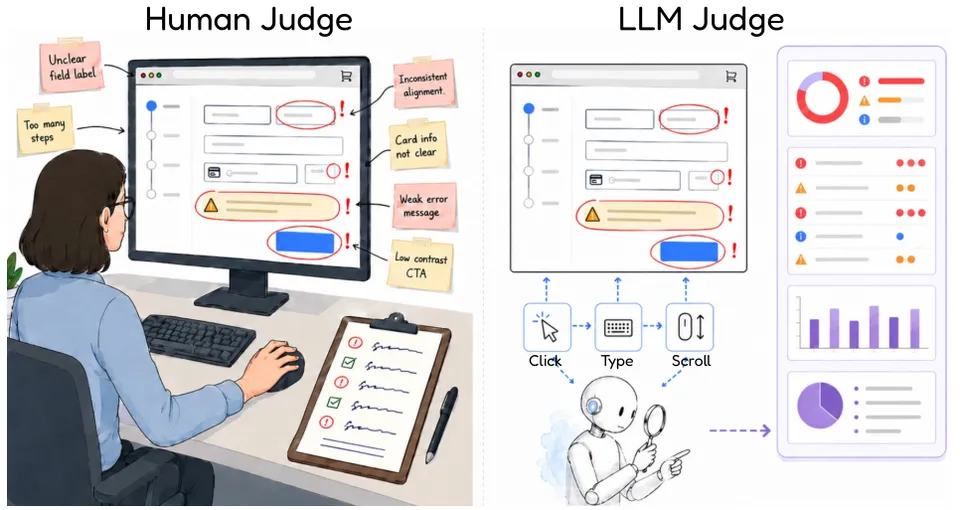
    UXBench: Measuring the Actionability of LLM-Generated UX Critiques

    Wenjie Wang, Yue Huang, Zipeng Ling, Han Bao, Hang Hua, Xiaonan Luo, Yu Jiang, Shiyi Du, Yuexing Hao, Xiaomin Li, Yuchen Ma, Dianzhuo Wang, Yanfang Ye, Xiangliang Zhang

  14. arXiv 2026

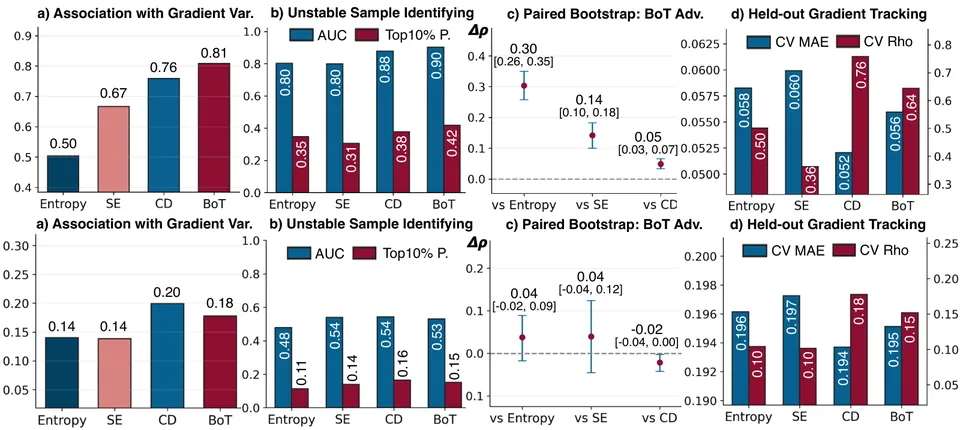
    Why Semantic Entropy Fails? Geometry-Aware and Calibrated Uncertainty for Policy Optimization

    Zheyuan Zhang, Kaiwen Shi, Han Bao, Zehong Wang, Tianyi Ma, Yanfang Ye

2025 2 papers 0 selected

  1. AAAI 2025 AAAI Conference on Artificial Intelligence

    LiD-FL: Towards List-Decodable Federated Learning

    Hong Liu, Liren Shan, Han Bao, Ronghui You, Yuhao Yi, Jiancheng Lv

  2. BMC MIDM 2025 BMC Medical Informatics and Decision Making

    CRISP: A Causal Relationships-Guided Deep Learning Framework for Advanced ICU Mortality Prediction

    Linna Wang, Xinyu Guo, Han Bao, Lihua Jiang, Li Zhao, Tao Zhu, Ziliang Feng

Curriculum Vitae

Education

  • University of Notre Dame Sep 2026 – Present

    Ph.D. in Computer Science · Advisor: Prof. Fanny Ye

  • Sichuan University Sep 2021 – Jun 2026

    B.Eng. in Cyber Science and Engineering

Research Experience

  • University of Notre Dame, Visiting Research Student Aug 2024 – Present

    Advisor: Prof. Xiangliang Zhang · Trustworthy Generative Models, LLM Alignment, Agent Evaluation

  • National University of Singapore, Summer Workshop Participant Jul 2024

    Advisor: Prof. Tianbai Ma · Cloud Computing, Network Traffic Analysis

Honors & Awards

  • Provincial Third Prize, China Undergraduate Mathematical Contest in Modeling Nov 2023

    Chinese Society for Industrial and Applied Mathematics (CSIAM)

  • Second-Class Scholarship (Top 10%) Sep 2023

    School of Cyber Science and Engineering, Sichuan University

Academic Service

  • Reviewer 2027

    International Conference on Learning Representations (ICLR 2027)

  • Reviewer 2027

    The ACM Web Conference (WWW 2027)

  • Reviewer 2026

    AAAI Conference on Artificial Intelligence (AAAI 2026)

  • Program Committee / Reviewer 2025

    NeurIPS 2025 Workshop on Socially Responsible and Trustworthy Foundation Models

esc

↑↓ move ↵ select type cite + title to copy BibTeX